How AI Crawlers Read Your Website
AI systems increasingly access websites to find information, understand pages, and provide answers to users. Understanding how AI bots crawl websites can help businesses make their content easier for AI-powered search and answer engines to discover and interpret.
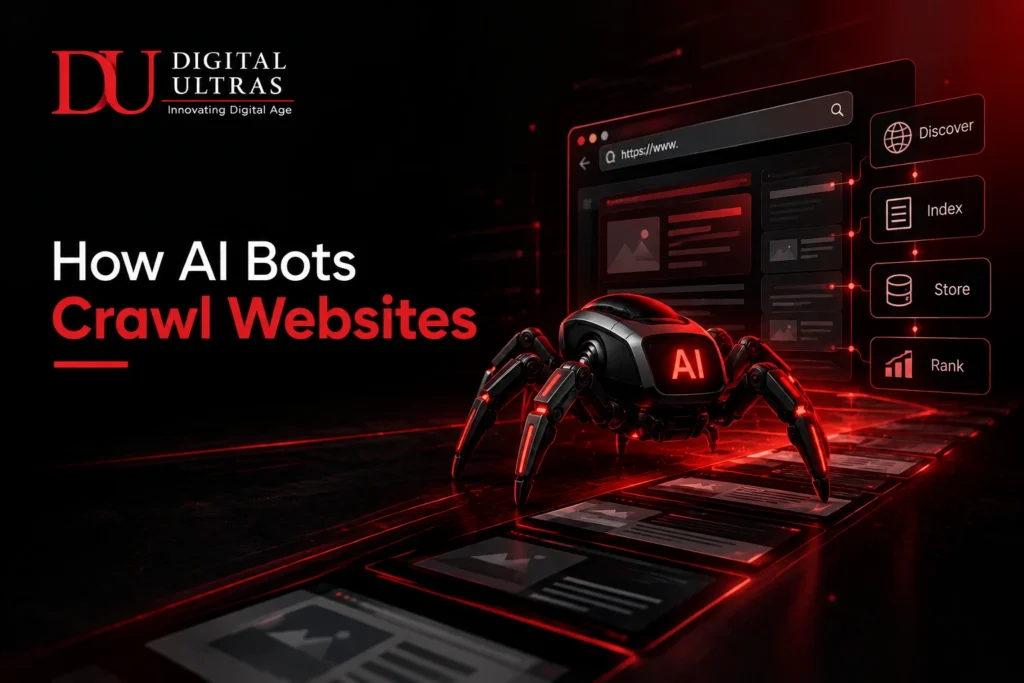
How AI Bots Crawl Websites
AI bots crawl websites by requesting accessible web pages, processing their content, and extracting information that can potentially be used in search or AI-powered experiences.
What is AI crawling? AI crawling is the process of automated systems accessing web pages to discover, read, and process online information.
Just like traditional search crawlers, AI-related crawlers can follow links, access pages, and analyze website content. Google explains that its crawlers use robots.txt rules to determine which parts of a website may be crawled.
What Do AI Crawlers Look For?
AI crawlers look for accessible, understandable, and relevant information that helps systems interpret the purpose and content of a webpage.
What is AI crawler access? AI crawler access refers to whether automated AI-related systems can reach and process content on a website.
Clear headings, useful paragraphs, internal links, structured information, and accessible pages can make content easier to process.
| Website Element | Why It Matters |
|---|---|
| Clear headings | Helps identify topics |
| Internal links | Helps discover related pages |
| Structured content | Improves content understanding |
| Robots.txt | Controls crawler access |
| Updated information | Keeps content relevant |
When learning how AI bots crawl websites, it is important to remember that different crawlers can have different purposes and access rules.
Robots.txt and AI Crawler Access
Robots.txt can control how certain crawlers access parts of your website.
Google states that its automated crawlers read and interpret robots.txt rules before crawling a website.
For example, website owners can use robots.txt to allow or disallow specific paths. Google also provides product-specific controls such as the Google-Extended token for certain Gemini-related uses.
Therefore, how AI bots crawl websites depends partly on the access rules configured by the website owner.
What Is an llms.txt File?
An llms.txt file is a proposed website file designed to provide AI agents with a curated overview of important website information and links.
What is an llms.txt file? An llms.txt file is a proposed Markdown-based file that gives AI agents structured information and links to useful website content.
The llms.txt proposal is intended to complement, rather than replace, robots.txt. While robots.txt communicates crawling preferences, llms.txt is designed to provide useful context and links for AI agents.
However, Google clarified in June 2026 that llms.txt is not required for Google Search and does not provide a ranking or visibility boost in Google Search.
How to Make Your Website Easier for AI Bots
Making your website technically accessible and clearly structured is a practical way to support AI and search-system understanding.
You can follow this simple process:
Step One: Check whether important pages can be crawled.
Step Two: Review your robots.txt rules and make sure valuable content is not unnecessarily blocked.
Step Three: Organize pages with descriptive headings and clear internal links.
Step Four: Keep important information accurate and updated.
Step Five: Consider an llms.txt file if it is useful for the AI systems or agents you want to support.
These steps help explain how AI bots crawl websites from both a technical and content perspective.
AI Crawlers vs Traditional Search Crawlers
AI crawlers and traditional search crawlers can both access web content, but their purposes and systems may differ.
| Traditional Search | AI-Powered Systems |
|---|---|
| Discover and index pages | Retrieve and interpret information |
| Focus heavily on search indexing | May focus on answering user questions |
| Use links and crawl signals | Can use multiple retrieval methods |
| Search ranking is central | Context and answer relevance can be important |
This is why understanding how AI bots crawl websites should be part of a broader technical SEO and AI-search strategy.
How AI Bots Crawl Websites: What Businesses Should Remember
The key to understanding how AI bots crawl websites is to focus on accessibility, clarity, structure, and accurate information rather than relying on one special file or technique.
Google’s current documentation makes clear that crawling controls such as robots.txt remain important, while Google has specifically stated that llms.txt is not needed for Google Search.
For businesses, the priority should be a technically sound website with useful content that can be accessed and understood by search engines and AI systems.
Conclusion
Understanding how AI bots crawl websites is becoming increasingly relevant as search evolves toward AI-powered answers and conversational experiences.
Businesses should focus on crawlable pages, clear website architecture, helpful content, internal linking, and appropriate crawler controls. An llms.txt file can be considered an additional resource for AI agents, but it should not be treated as a guaranteed Google ranking or AI visibility factor.
For DG Ultras, understanding AI crawler access and how AI bots crawl websites can help businesses build a stronger technical foundation for modern search and AI-driven discovery.
